Thai Resume
TH
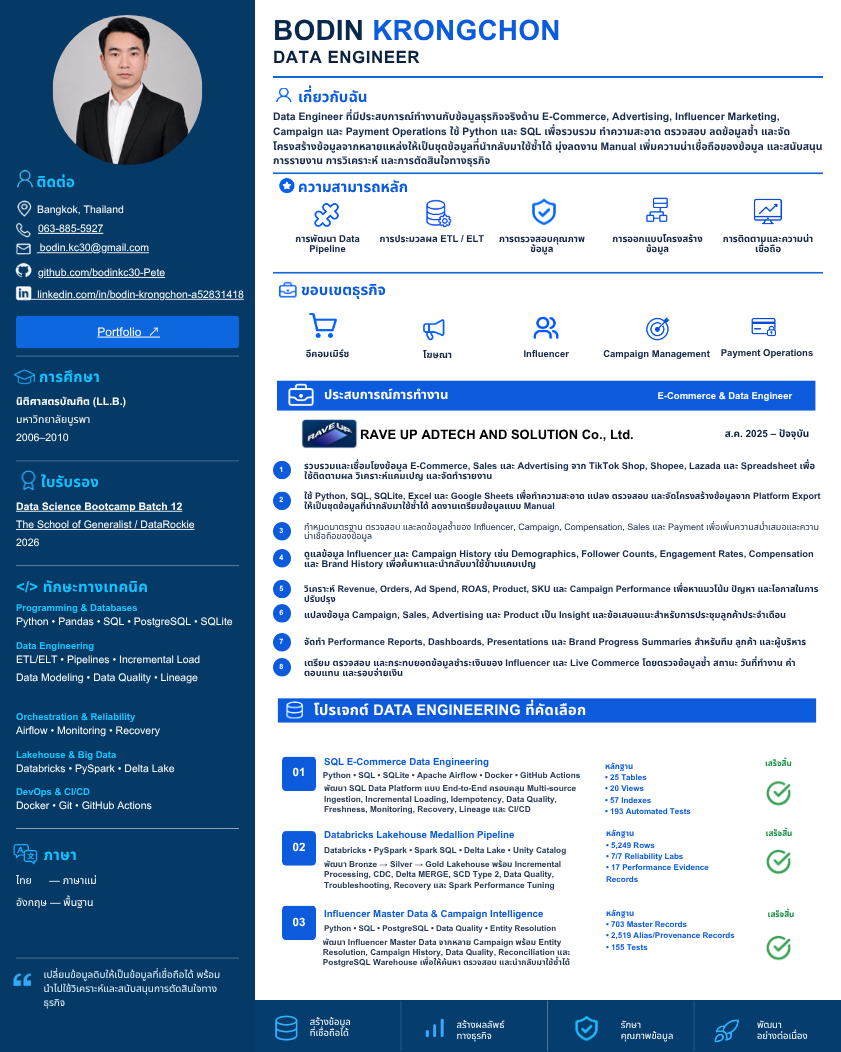
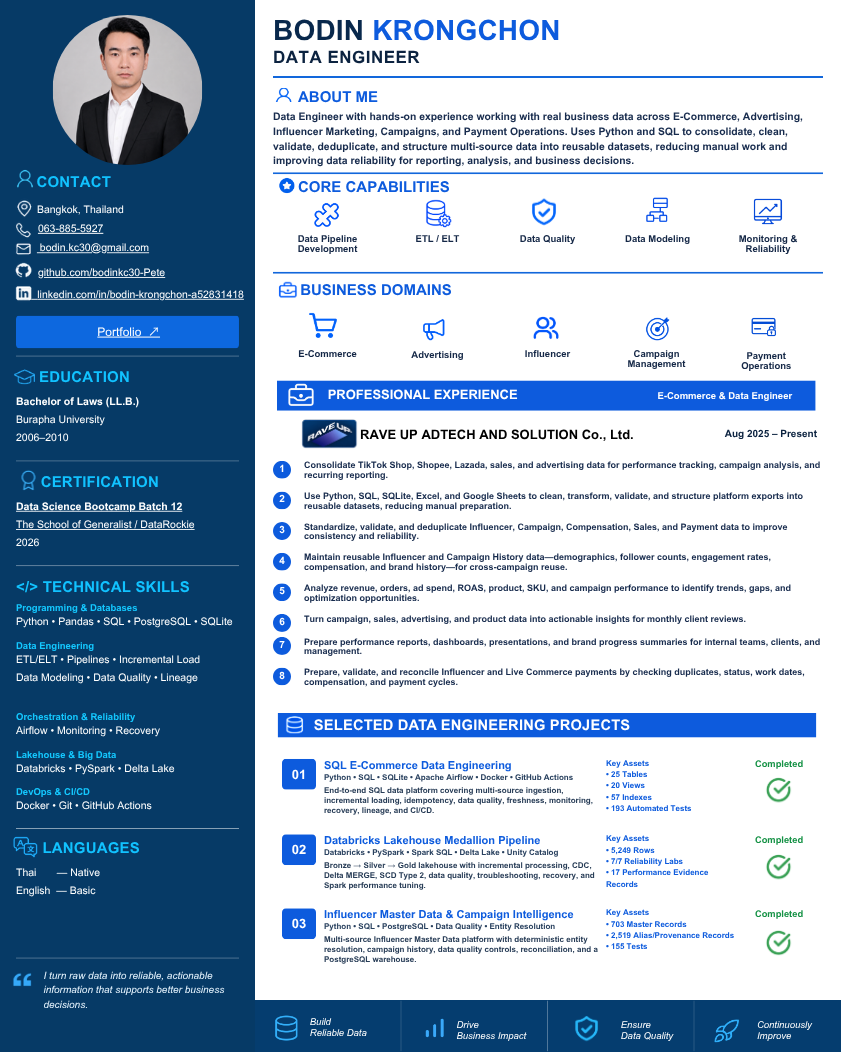
View or download image and PDF versions of my Thai and English resumes.
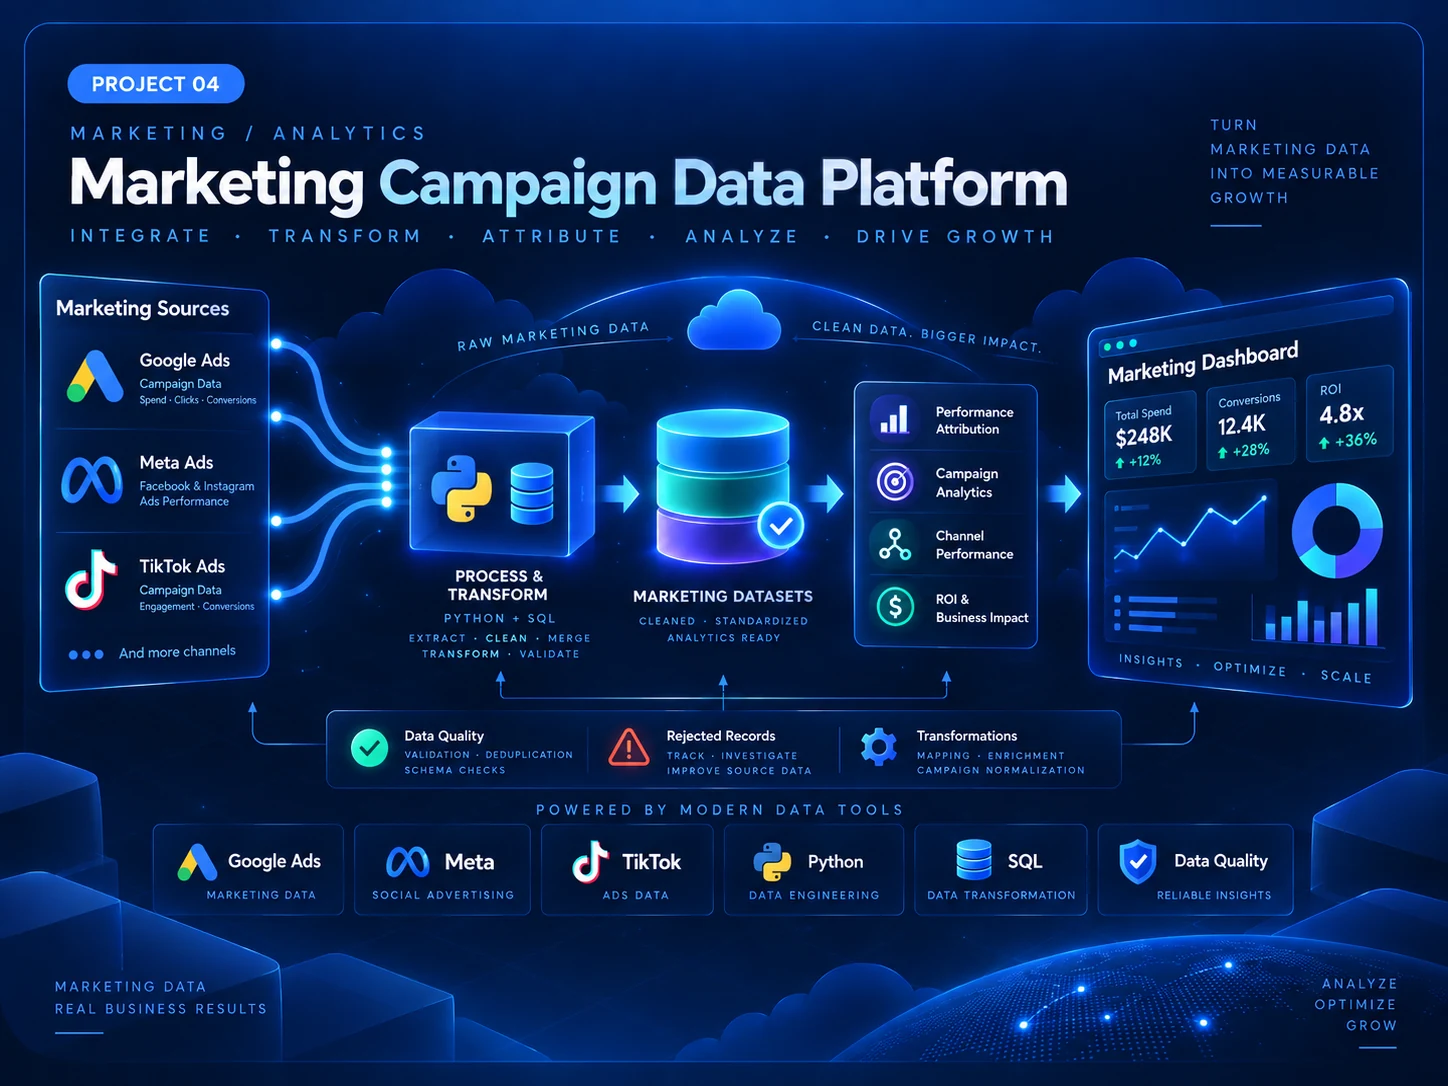
Consolidated e-commerce, sales, and advertising data from TikTok Shop, Shopee, and Lazada to support performance monitoring, campaign analysis, and monthly reporting.
Structured scattered operational data from spreadsheets and platform exports into reusable datasets using Excel, Google Sheets, SQLite, SQL, and Python, improving accessibility and reducing repetitive manual preparation.
Cleaned, standardized, validated, and deduplicated influencer, campaign, compensation, sales, and payment data to improve consistency, reduce redundant records, and support reliable downstream analysis.
Maintained reusable influencer profiles and campaign history, including demographics, follower counts, engagement rates, compensation, and prior brand activities, to support campaign matching and reduce repeated sourcing work.
Monitored sales and advertising performance using revenue, orders, ad spend, product performance, and ROAS-related metrics to identify trends, performance gaps, and opportunities for campaign improvement.
Analyzed product, SKU, and campaign performance to identify best-selling products, advertising efficiency, underperforming campaigns, and opportunities to improve budget allocation and product focus.
Translated campaign, sales, advertising, and product data into actionable insights and recommendations for monthly client reviews, helping brands identify performance issues, opportunities, and next actions.
Prepared validated monthly performance datasets, analytical summaries, and reporting-ready outputs to support dashboards, reports, presentations, client reviews, and management decision-making.
Prepared and reconciled influencer and live-commerce payment data by brand and individual, checking duplicate records, payment status, work dates, compensation, and payment-cycle requirements before management processing.
Supported e-commerce, advertising, influencer, payment, and project operations in a lean startup environment, applying data-driven workflows to reduce manual effort, improve turnaround time, and enable teams to reuse trusted information.
DATA ENGINEER
Build • Operate • Improve
I build reliable, scalable, production-style data systems that turn real business data into trusted, actionable information.
Databricks Lakehouse built on Apache Spark with Bronze-Silver-Gold, Delta Lake, CDC, SCD Type 2, data quality, reliability labs, monitoring, CI, and measured performance tuning.
Production-style data engineering projects with real-world business context and verified evidence.
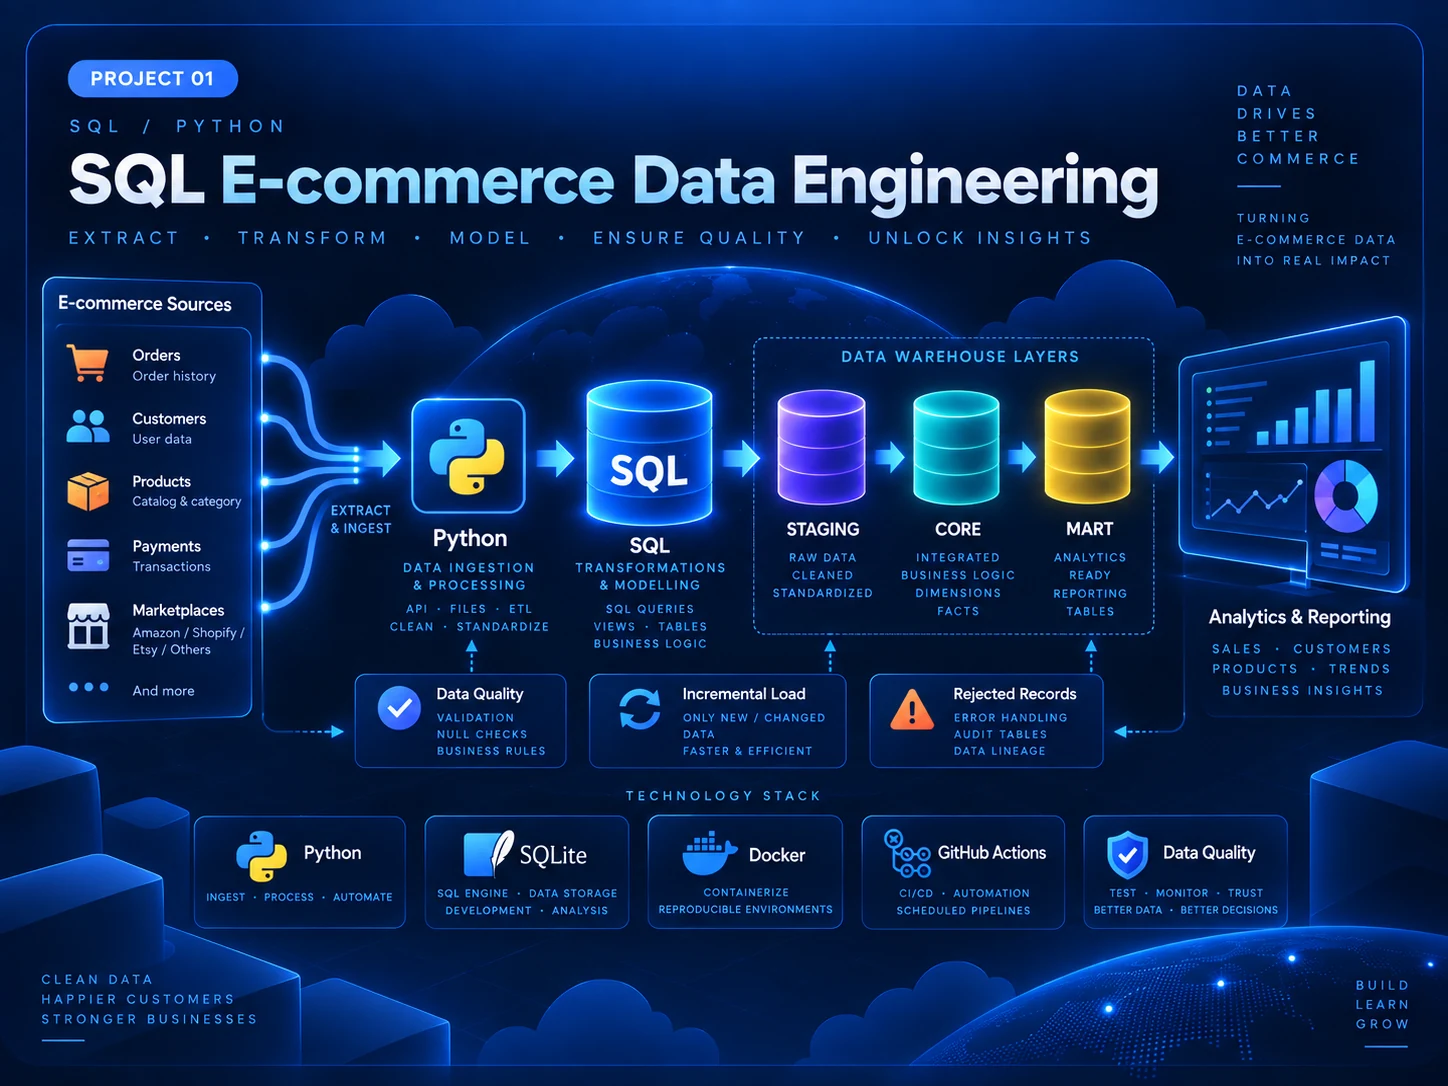
Reliable SQL data platform with incremental load, data quality, monitoring, API serving, and recovery.
Databricks Lakehouse on Apache Spark with Delta Lake, Bronze-Silver-Gold, CDC, SCD2, data quality, reliability labs, CI, and measured Spark optimization.
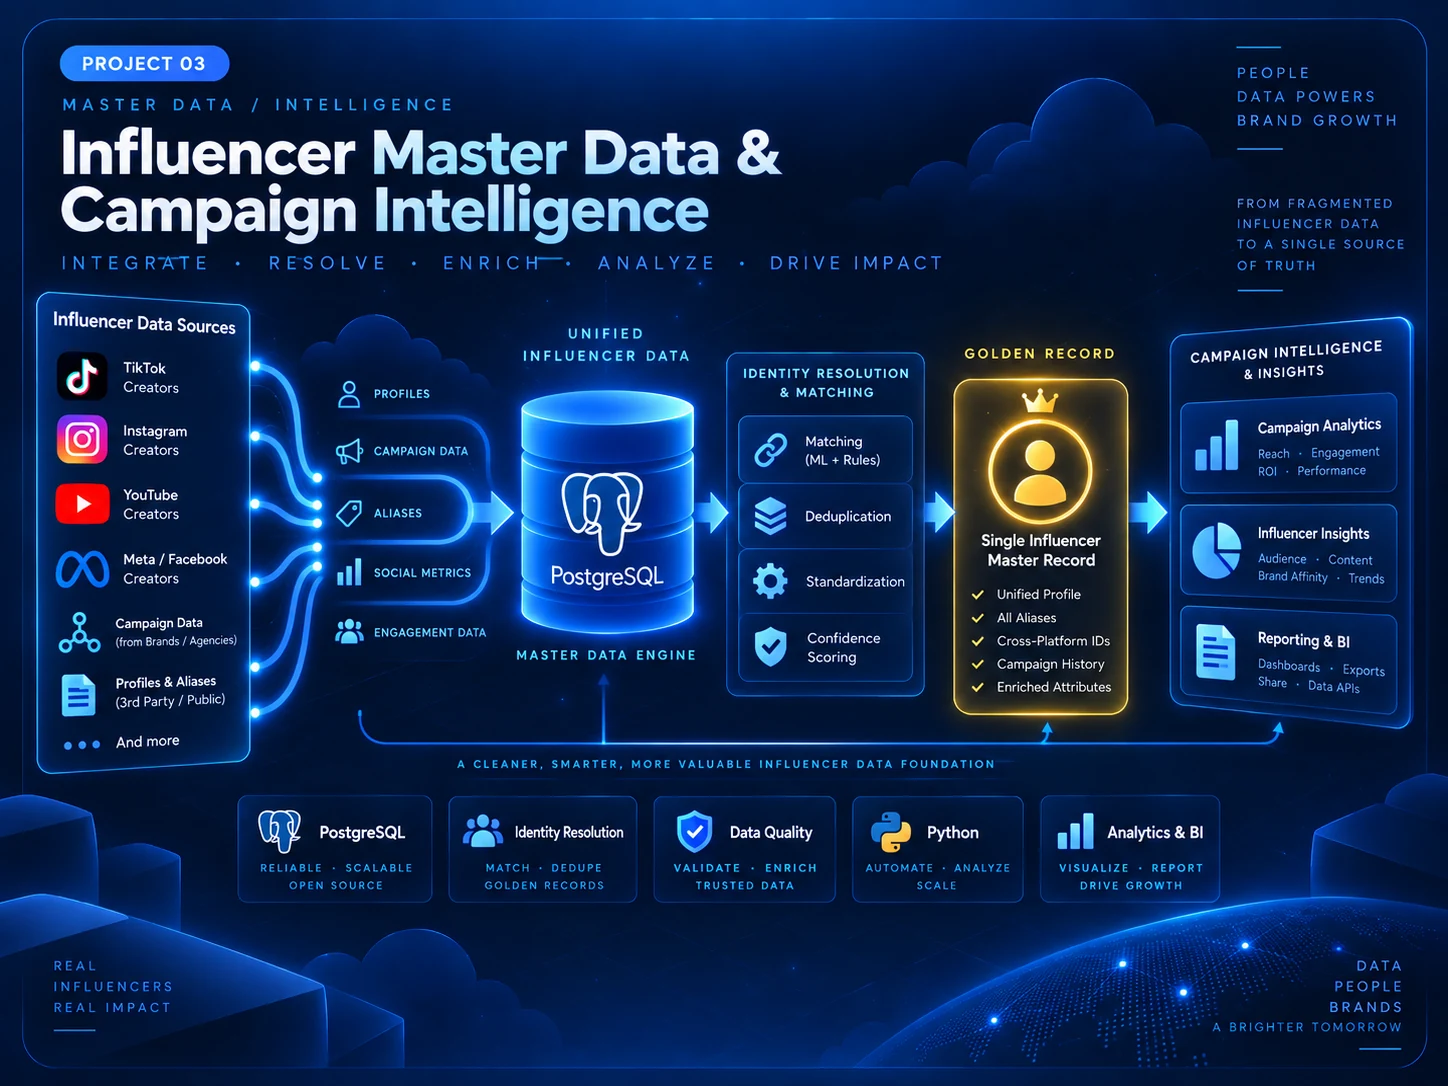
Governed influencer master data connecting source provenance, campaign history, and explainable matching decisions.
Payment-data validation, rejected-record routing, SQLite analytics, and privacy-safe portfolio outputs.
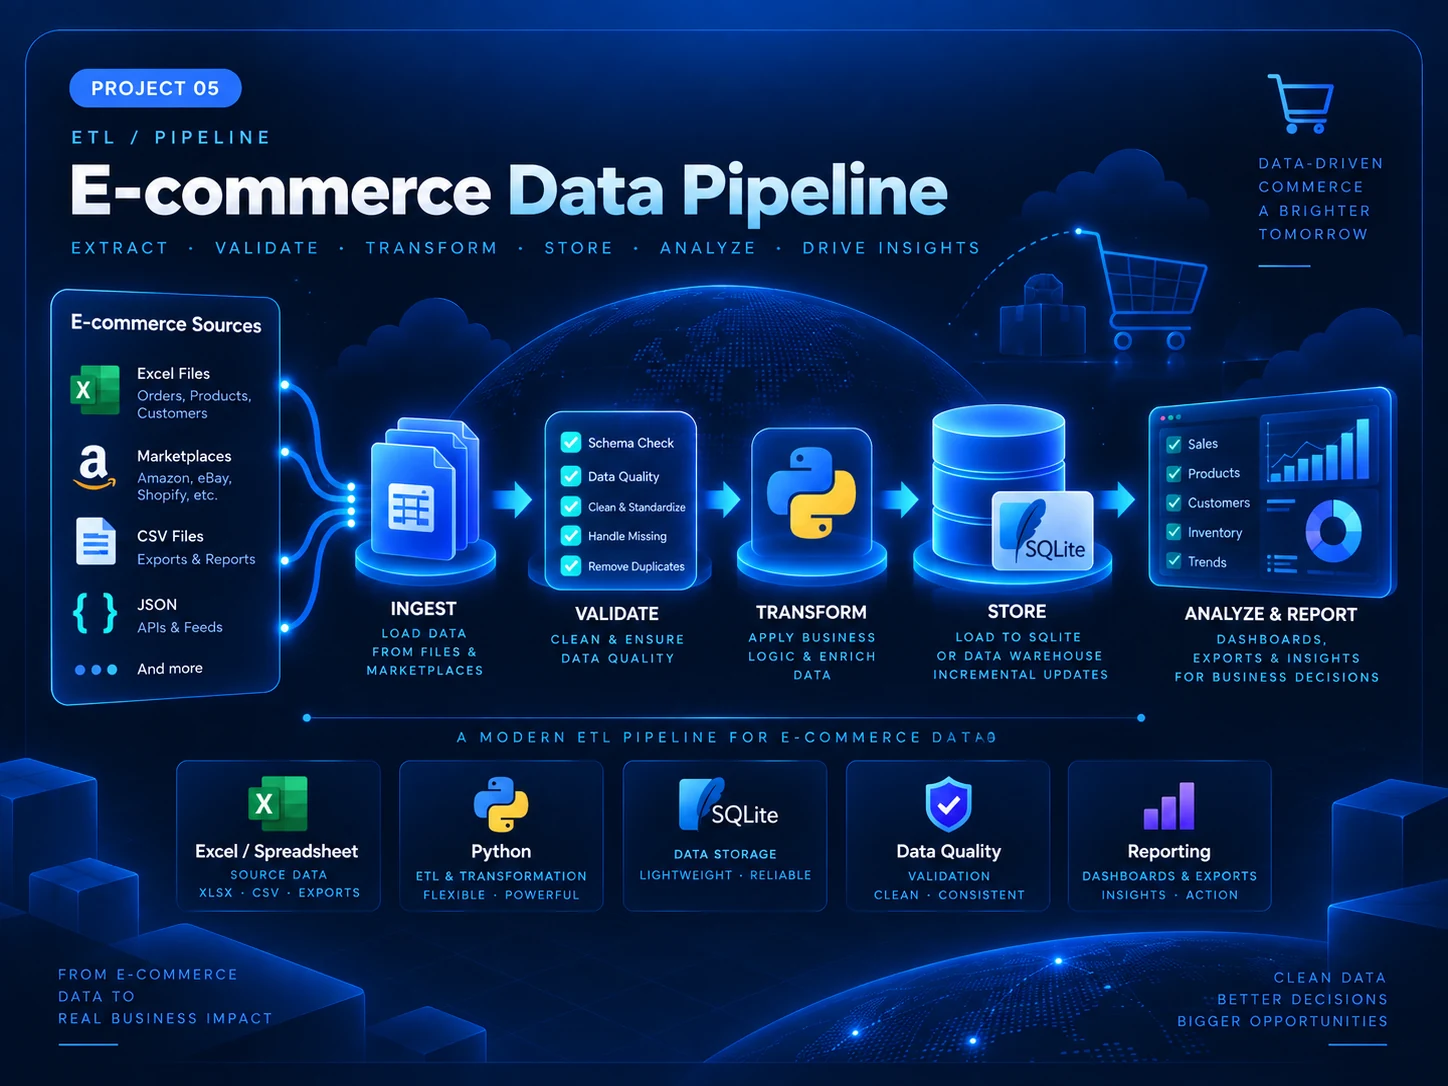
Multi-source Excel pipeline with validation, transformation, SQLite analytics, and portfolio-safe outputs.
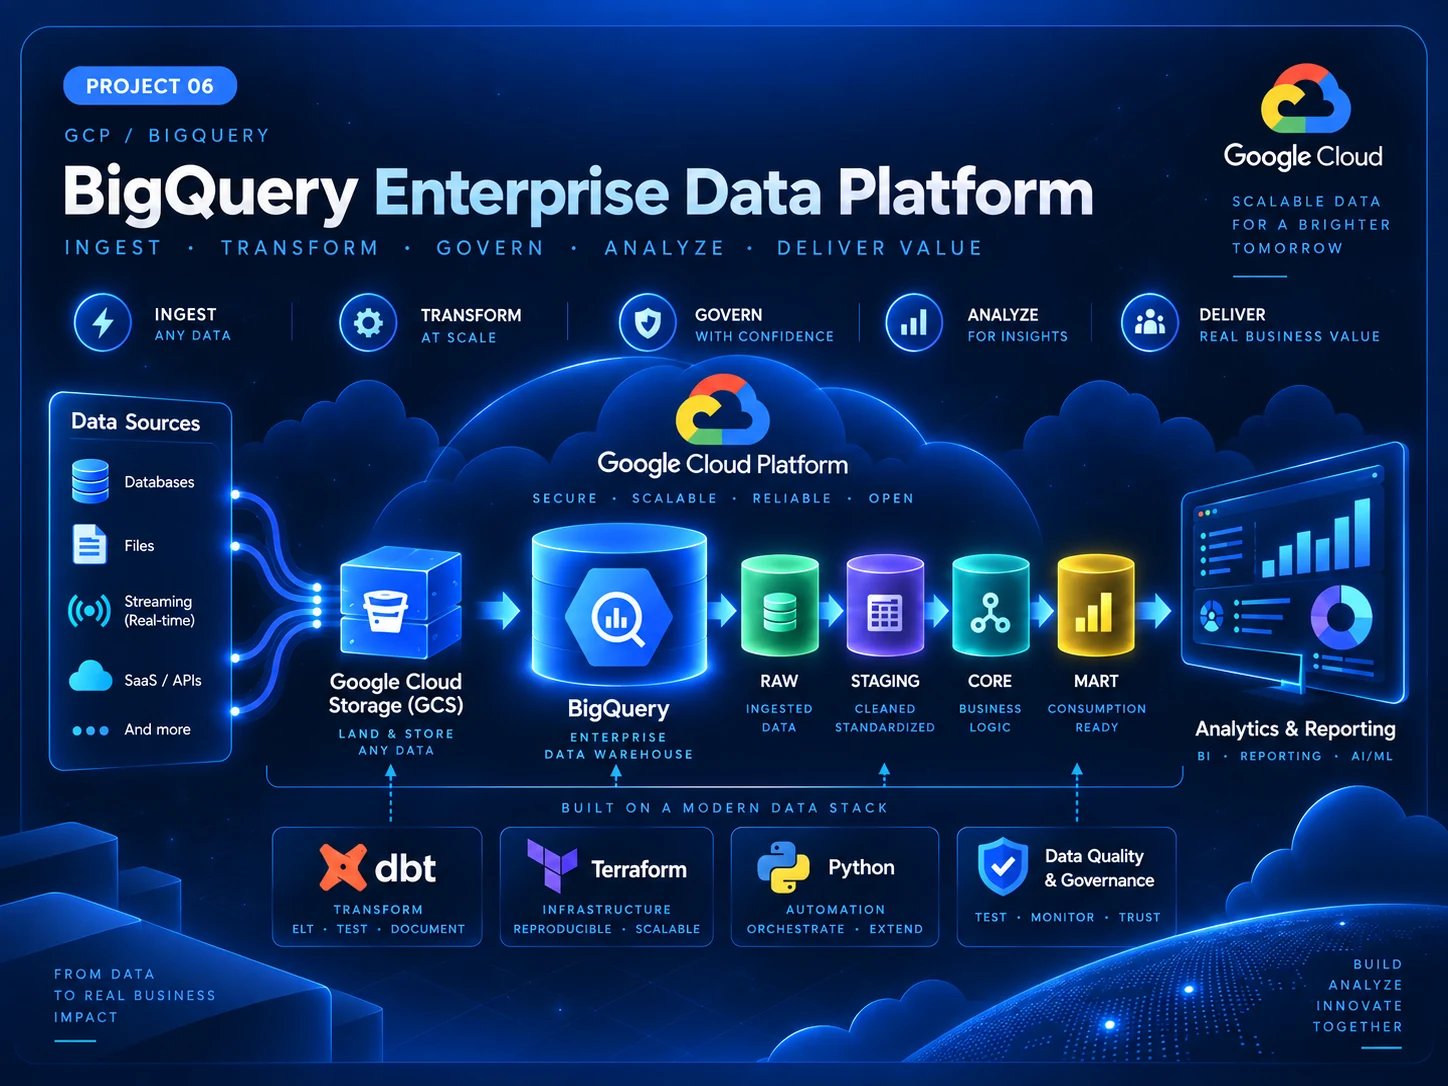
Production-oriented GCP/BigQuery platform with layered warehouse modeling, dbt, reconciliation, security, Terraform, and CI/CD.
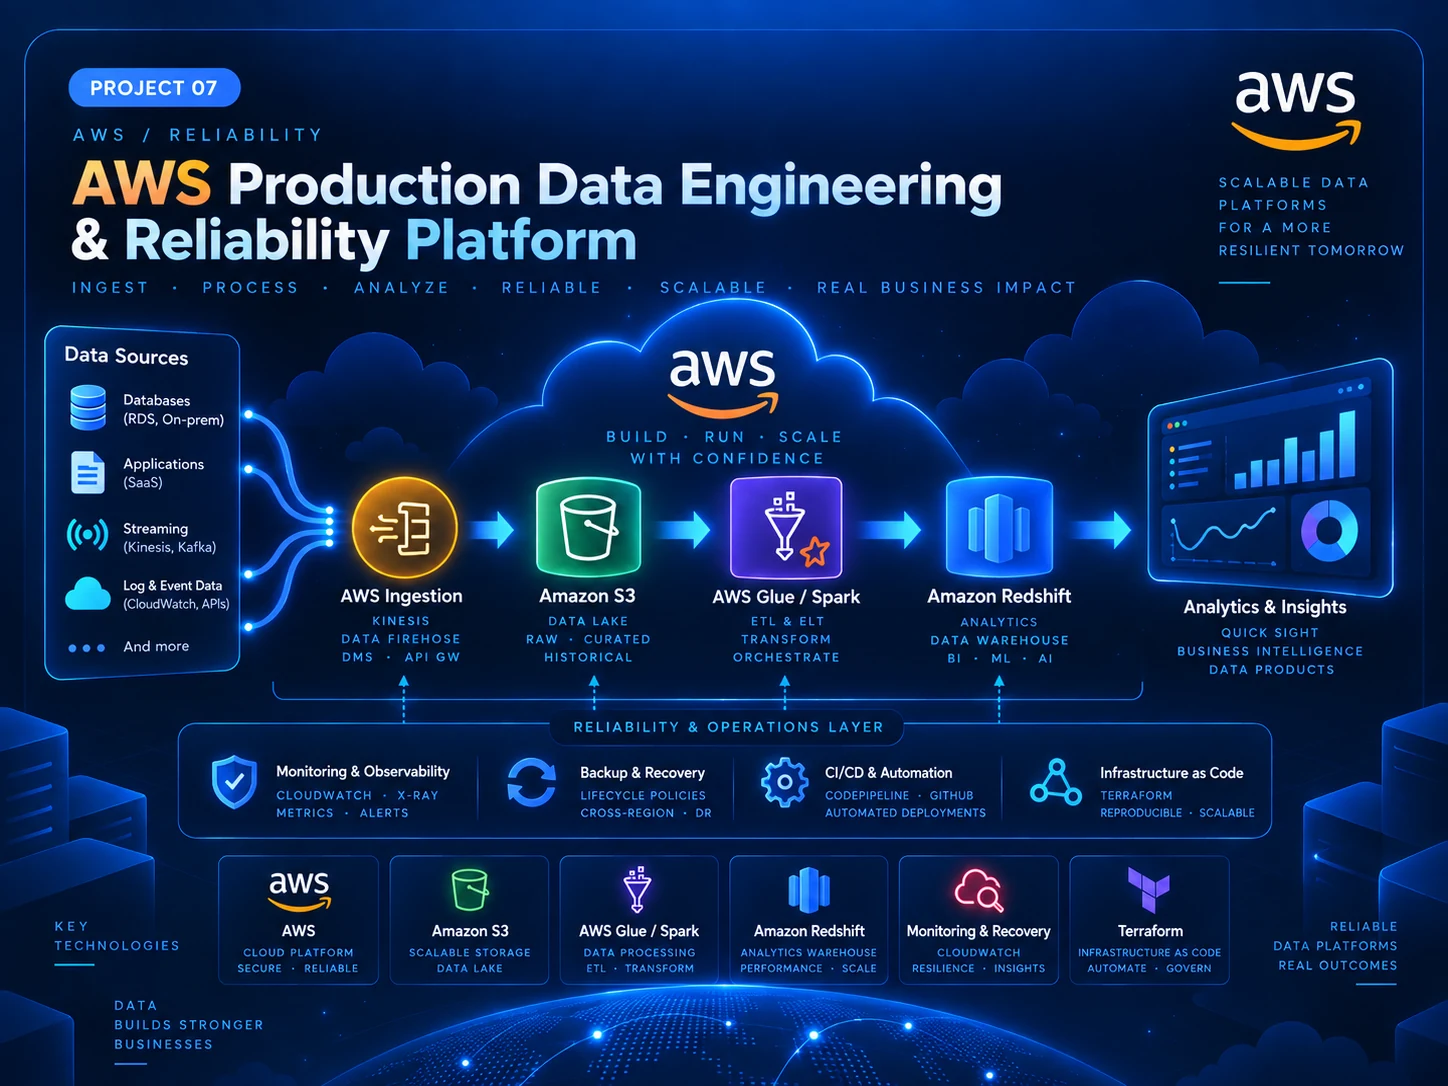
AWS data platform for retail, vending, and payment workflows with SQL, Python, Glue, S3, Redshift, orchestration, data quality, and reliability engineering.
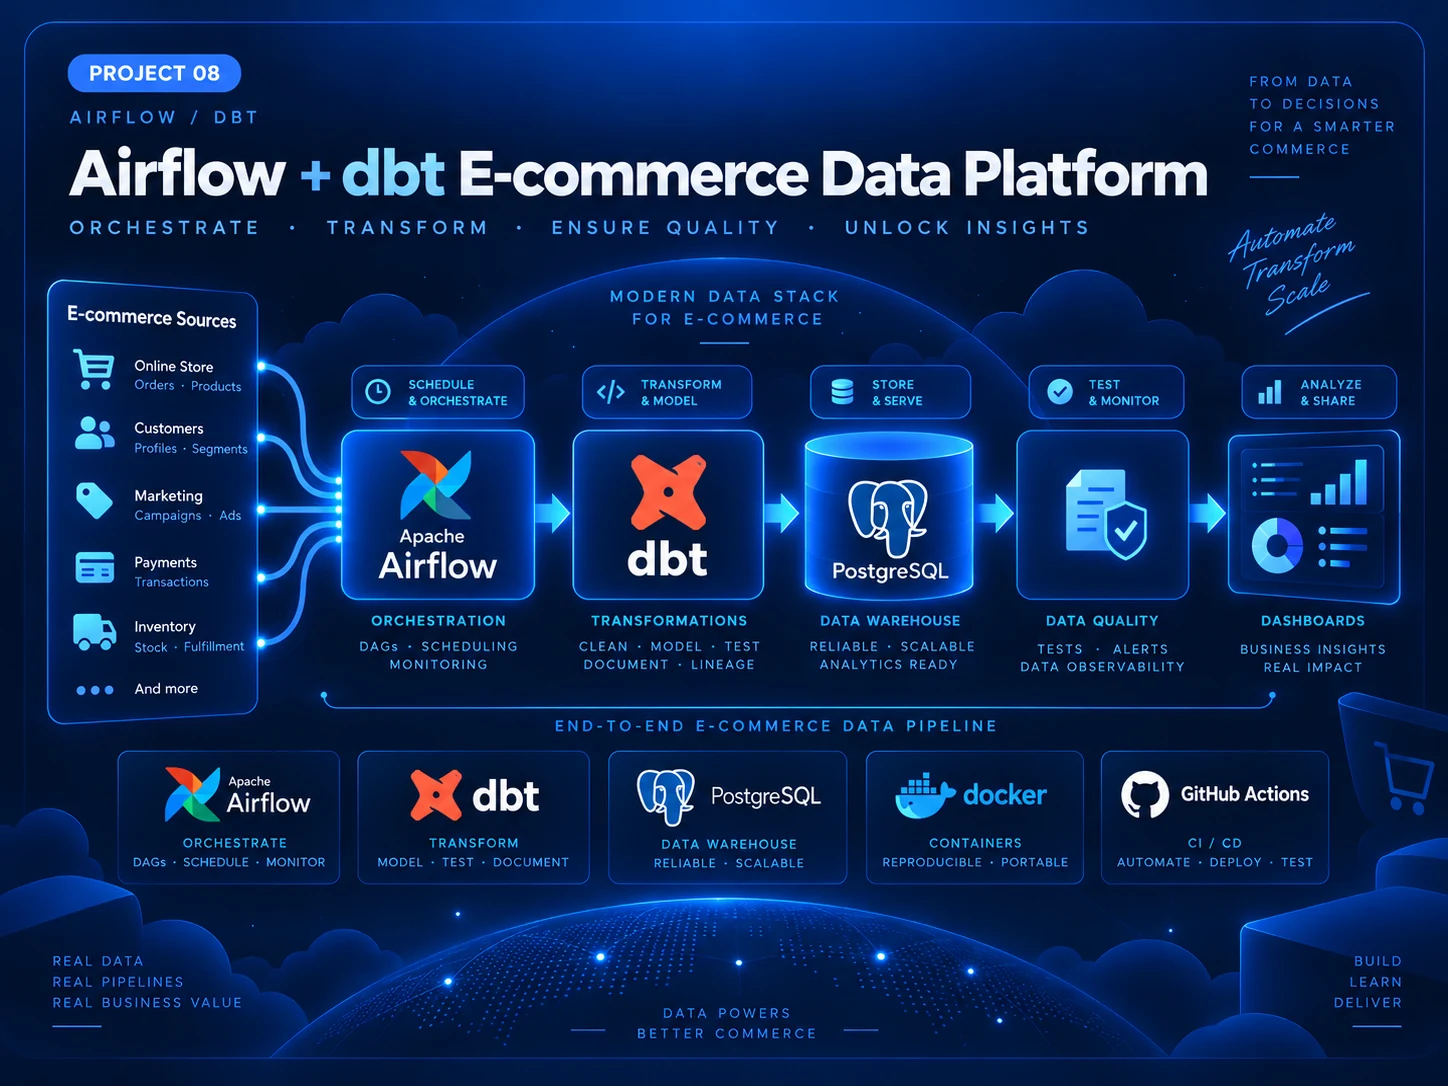
Production-oriented e-commerce platform with Airflow orchestration, PostgreSQL, dbt warehouse layers, data quality, monitoring, recovery drills, Docker, and CI.
Build beyond the happy path: data quality, monitoring, recovery, lineage, CI/CD, and performance evidence.
Capabilities grounded in completed projects, from ETL and modeling to reliability and serving.
Real operational context across e-commerce, influencer, campaign, payment, and reporting workflows.
Open to Data Engineering opportunities and technical conversations.
Send Message →“Data is not just numbers. It is better decisions.”
Eight portfolio projects shown with real pipeline runs, reliability screenshots, test output, CI checkpoints, and repository evidence. Metrics are recorded checkpoints, not a claim that every system is running live.
A reliability-focused SQL platform with incremental loading, idempotency, quality and freshness gates, monitoring, recovery, Airflow, read-only API serving, Docker, and CI.
A Databricks Lakehouse built on Apache Spark that demonstrates Delta Lake medallion architecture, CDC, SCD Type 2, data quality, controlled failure labs, monitoring, troubleshooting, CI, and measured Spark performance tuning.
A deterministic Master Data and PostgreSQL project that resolves fragmented influencer identities into a traceable Golden Master, preserves campaign and performance history, and supports explainable human-reviewed matching.
Python/SQLite payment pipeline with rejected-record routing and six published outputs. Recorded DQ: 268 rows, 97 missing post dates, and 35 missing payment statuses; these are reported, not silently filled. Private source data is required for a full rerun; no hosted CI is configured.
Python/Pandas Excel ETL with SQLite analytics and five published outputs. The recorded 105-row sample has zero findings in its configured DQ report. Raw Excel files are private; Docker and hosted CI are not configured in this repository.
GCP/BigQuery warehouse with dbt, Terraform, incremental processing, reconciliation, governance and synthetic financial operations. Published runtime evidence records 12/12 checks and eight RAW tables. Public CI checks publication safety, Python syntax and Terraform formatting; it does not rerun the cloud workload.
A production-style AWS data engineering platform covering retail, vending, and payment data with SQL/Python pipelines, Glue and PySpark transformations, S3 landing, Redshift warehousing, dbt, Airflow, Terraform, data quality, monitoring, security, recovery, and CI/CD evidence.
Eight source contracts, PostgreSQL, Airflow and dbt with monitoring, recovery drills and Docker. Hosted CI checkpoint: 370 service-free tests, 37 PostgreSQL tests and 257 dbt build results passed. AWS infrastructure is reference/plan evidence; live ECS/RDS/ALB runtime is not deployed.
The portfolio proves that systems can be tested, observed, diagnosed, recovered, and verified — not only executed successfully.
Contracts, thresholds, reconciliation, quarantine, validation, and regression checks.
Dataset lineage, runtime lineage, asset registry, PII classification, masking, and hashing.
Run audits, step telemetry, SLA signals, alert fingerprints, occurrence history, and lifecycle.
Controlled failures, retry, RCA, recovery contracts, backfill, and recovery validation.
Query plans, benchmark evidence, indexing, Spark tuning, and regression protection.
GitHub Actions, automated tests, Docker validation, reproducible runtime checks, and release evidence before delivery.
Capability cards describe what I can build and operate today — not a future learning roadmap.
 Python
 SQL
 PostgreSQL
 Docker
 Airflow
 Databricks
 Git / CI
Batch • Incremental • CDC • SCD
Relational • Warehouse • Medallion
Airflow • Scheduling • Recovery
Validation • Reconciliation • Freshness
FastAPI • Read-only access • Safe outputs
Docker • GitHub Actions • Reproducibility
SQL • PostgreSQL • SQLite
E-commerce • Influencer • Campaign • Payment
Monitoring • Alerts • Retry • Recovery
GCP/BigQuery • AWS • Terraform
Portfolio projects extend recurring operational data pain points into engineering labs. They do not claim that every portfolio technology is deployed in production at the company.
RAVE UP ADTECH AND SOLUTION Co., Ltd. · Bangkok, Thailand · Hybrid
I connect recurring operational data work with reusable engineering practices that reduce manual preparation and improve trust in analysis.
TikTok Shop, Shopee and Lazada data consolidated into reusable datasets and reporting workflows.
Clean, standardize, validate and deduplicate influencer, campaign, sales, compensation and payment records.
Analyze sales, advertising, product, SKU and campaign performance to surface trends and opportunities.
Turn campaign and commerce data into client insights, dashboards, presentations and next-action recommendations.
Prepare and reconcile payment data while supporting e-commerce, influencer and project operations in a lean team.
Formal education and structured learning that support my engineering practice.
Hands-on data science and engineering practice through structured projects.
Legal foundation strengthened analytical reasoning, structured problem solving, and communication.
My portfolio connects hands-on e-commerce, influencer, campaign, payment, and reporting work with reliable data engineering. The goal is to reduce repetitive preparation, improve data trust, and give more time back to analysis and better decisions.
I prefer systems that are observable, recoverable, testable, and explainable — not just pipelines that happen to finish successfully.
Start with the business problem and the data pain behind it.
Create reusable systems that can be operated and extended.
Trace failures through evidence and verify recovery.
Keep future learning separate from verified capability.
Only credentials with a confirmed public link are shown here.
View my Thai and English resumes.
For Data Engineering opportunities, portfolio review, or technical conversations, use the channels below.
Send Message→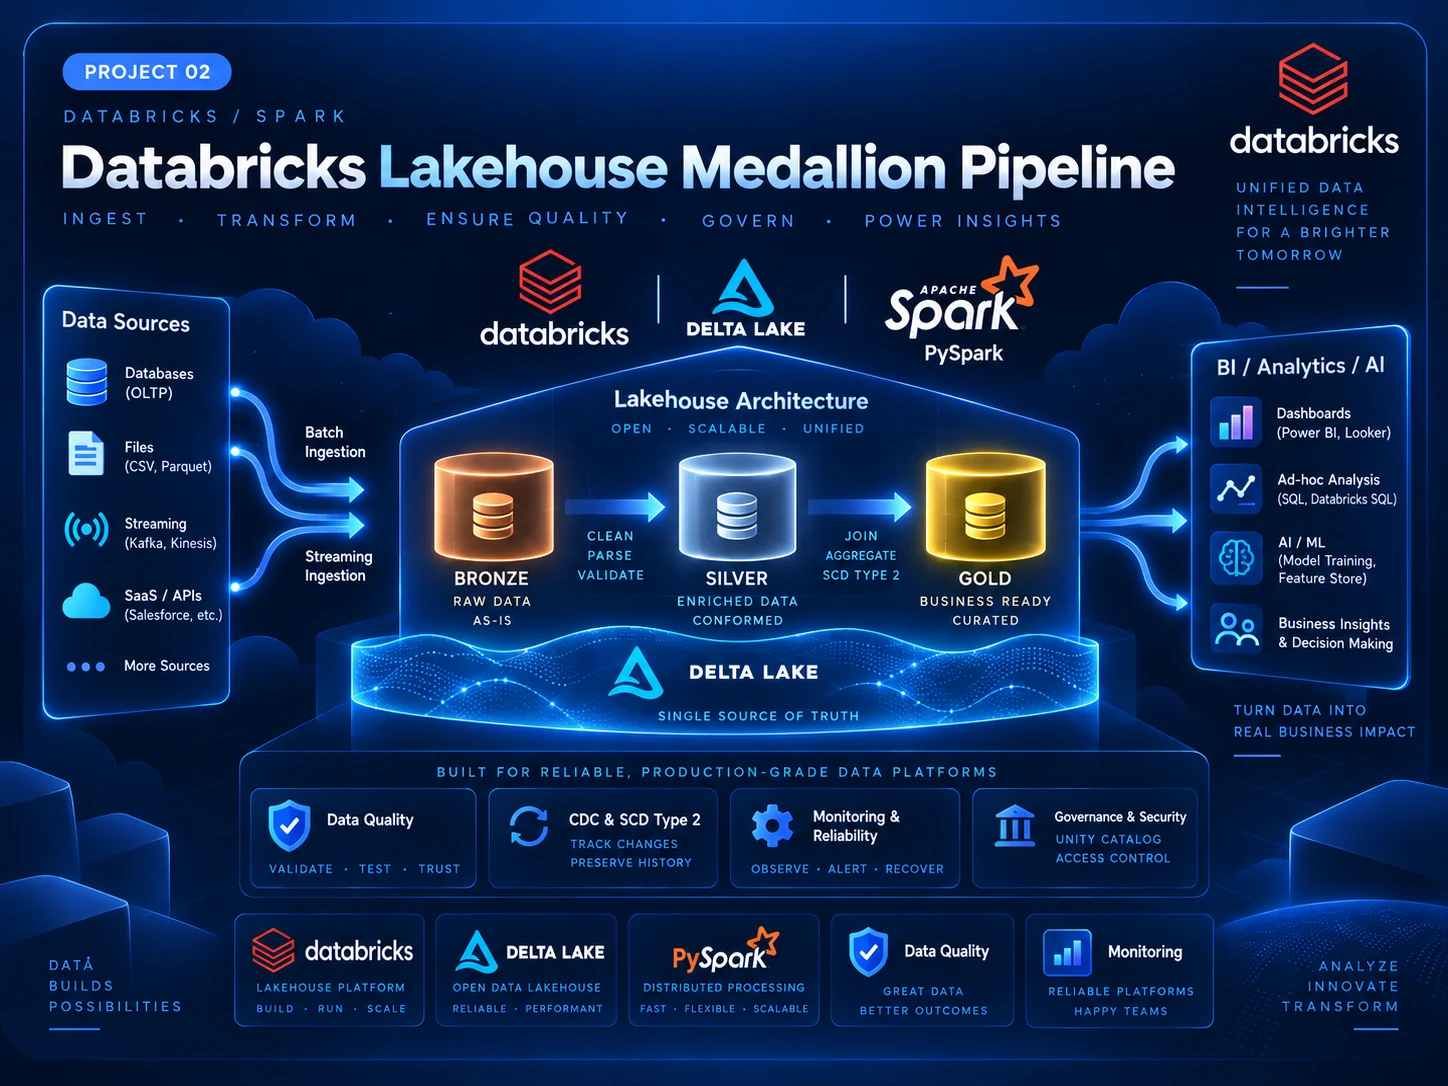
 SQLite